PDF to Markdown OCR Converter
Convert a scanned or digital PDF into a Markdown (.md) file: the same text as the .txt download, in the same order, as paragraphs. Supports 100+ text languages.
PDFs require a free account and use pages. View limits and pricing.
Drop your file here
PDF, PNG, JPG, WebP, BMP, HEIC
PDF up to 1 GB · images up to 20 MB
Tips for a clear photo
- Lay the page flat.
- Use even light, with no shadows.
- Turn off the flash to avoid glare.
- Fill the frame with the page.
A real scan and its Markdown
This is a real typewritten letter. The Markdown beside it is the file FastOCR writes for it, shown as raw text. The lines of each paragraph are joined, and nothing else is added: the page number and the “SECRET” marking stay as their own paragraphs. It is the complete file for this one page.
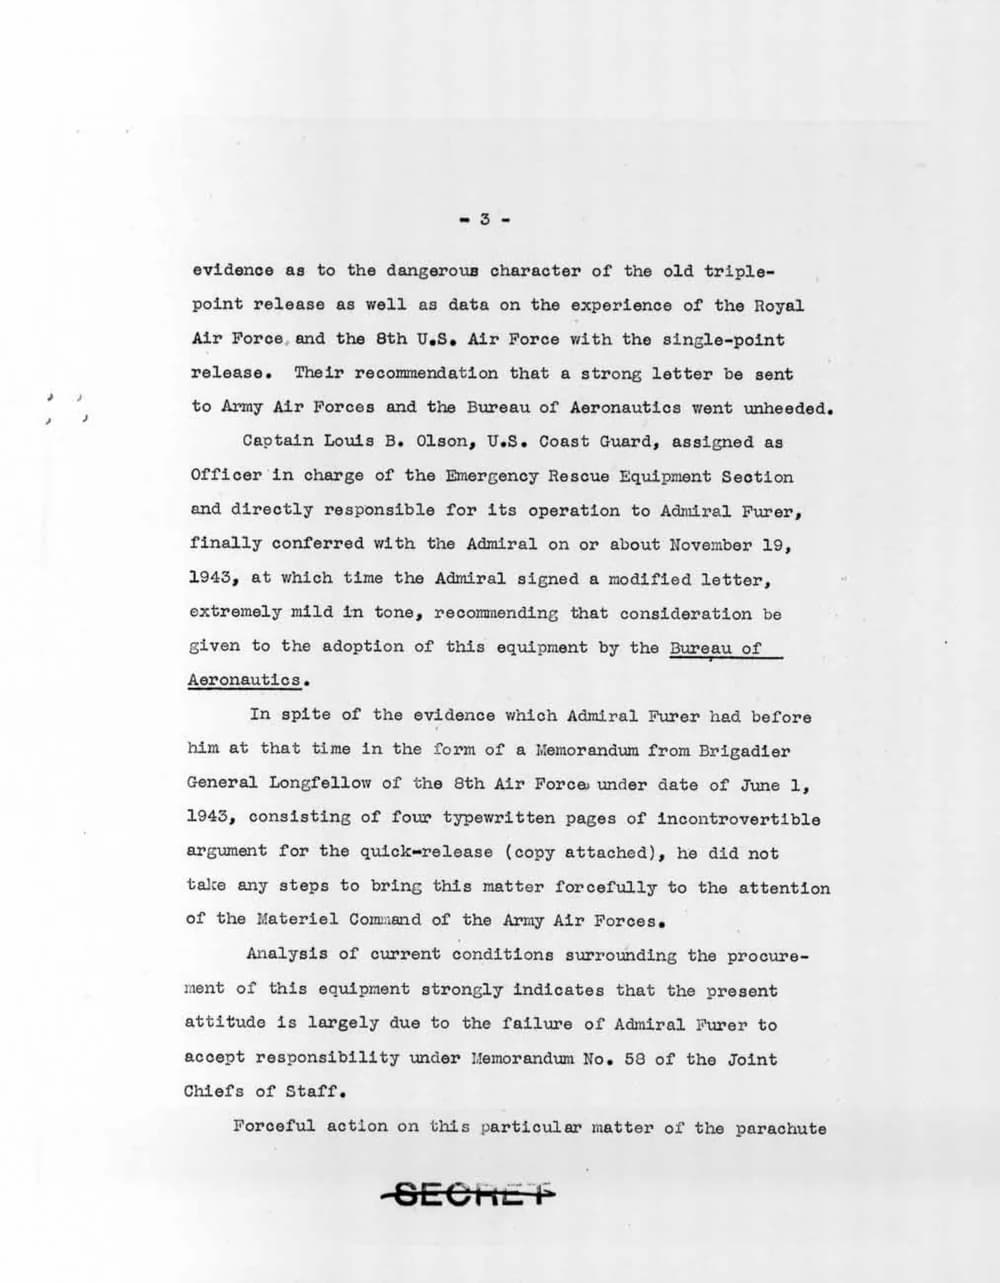
-3-

evidence as to the dangerous character of the old triple-point release as well as data on the experience of the Royal Air Force, and the 8th U.S. Air Force with the single-point release. Their recommendation that a strong letter be sent to Army Air Forces and the Bureau of Aeronautics went unheeded.

Captain Louis B. Olson, U.S. Coast Guard, assigned as Officer in charge of the Emergency Rescue Equipment Section and directly responsible for its operation to Admiral Furer, finally conferred with the Admiral on or about November 19, 1943, at which time the Admiral signed a modified letter, extremely mild in tone, recommending that consideration be given to the adoption of this equipment by the Bureau of Aeronautics.

In spite of the evidence which Admiral Furer had before him at that time in the form of a Memorandum from Brigadier General Longfellow of the 8th Air Force under date of June 1, 1943, consisting of four typewritten pages of incontrovertible argument for the quick-release (copy attached), he did not take any steps to bring this matter forcefully to the attention of the Materiel Command of the Army Air Forces.

Analysis of current conditions surrounding the procure-ment of this equipment strongly indicates that the present attitude is largely due to the failure of Admiral Furer to accept responsibility under Memorandum No. 58 of the Joint Chiefs of Staff.

Forceful action on this particular matter of the parachute

SECRET
How to convert a scanned PDF to Markdown
- Choose your PDF. Use a free account to upload the scanned or digital document.
- Wait for text extraction. FastOCR processes the pages and prepares the result. Check names and numbers against the original.
- Download Markdown. Open the .md file in any editor, or paste it into ChatGPT, Claude or a notes app.
What the Markdown file contains
- The same words as the .txt download, in the same order.
- Pages that FastOCR can reflow become paragraphs. Pages with tables, forms or other line-by-line layouts keep every line, as one block with line breaks.
- PDF pages are separated by
<!-- page N -->comments only when FastOCR can verify the page boundaries. The first page has no marker, and numbers can skip blank pages. - Characters that Markdown would read as formatting are backslash-escaped, so the text shows as written.
- No headings, lists or tables are added, and page headers and footers are not removed.
- Pictures, photos, diagrams and charts are not copied into the Markdown. Text recognized inside them stays as text.
Scanned & native PDFs
AI reads text from scanned page images. Native PDFs have text extracted directly.
Markdown, text, Word or searchable PDF
Download the result as a Markdown (.md) file, plain text, a Word file or a searchable PDF, or copy the text directly.
RTL preserved
Arabic, Urdu, and Farsi text direction is maintained correctly in the output.
Multi-page support
Process documents with hundreds of pages. Large PDFs are chunked and processed in parallel.
Encrypted & auto-deleted
Files are encrypted at rest and permanently deleted after 30 days.
Native PDFs read directly
Digital PDFs have their text read from the file itself.
Frequently asked questions
How does PDF to Markdown conversion work?
Upload your PDF and FastOCR reads the text with AI-powered OCR. For scanned PDFs, the AI reads the page images. For native PDFs, text is extracted directly from the document. When it finishes, download the result as a Markdown (.md) file, plain text, a Word file or a searchable PDF.
What is in the Markdown file?
The same words as the plain-text download, in the same order. Pages that FastOCR can reflow get paragraphs. Pages with tables, forms or other line-by-line layouts keep every line as one block, so nothing runs together. Characters that Markdown would read as formatting are backslash-escaped, so the text shows as written. Pages are separated by <!-- page N --> comments only when FastOCR can verify the page boundaries. The first page has no marker, numbers can skip blank pages, and edited or translated text has none.
Does it detect headings, tables or lists?
No. The Markdown has paragraphs only. It does not add headings, lists, tables or emphasis, and it does not remove page headers, footers or page numbers. A table gives you its words, one line each, so expect to rebuild the table yourself.
Are pictures, diagrams and charts included?
No. Photos, diagrams and charts are not copied into the Markdown. Text that FastOCR recognizes inside them stays as ordinary text, but what they show is not kept. This is a text export, not a layout-faithful converter. For a copy that looks like the original, download the searchable PDF.
Is scanned PDF to Markdown conversion free?
Start with a free account and use its document-page allowance. PDFs require an account; image OCR is separate and does not use the PDF page allowance. For more PDF pages, see the page packs and subscriptions on our pricing page.
Does it work with Arabic or Urdu PDFs?
Yes. FastOCR supports 100+ languages including Arabic, Urdu, Farsi, and Hebrew. The text keeps its right-to-left characters in reading order.
What is the file size limit?
PDFs up to 1 GB and 10,000 pages are supported. Large documents are processed in chunks. See the pricing page for the document-page allowance on your plan.
Can I translate or use AI Polish on a PDF?
Translation and AI Polish are follow-up actions for single-image OCR, not PDFs. To use them for one PDF page, upload a photo or screenshot of that page as an image.
Only need plain text? Try PDF to Text. Starting from a photo or screenshot? Use Image to Markdown. Feeding an AI model? See PDF OCR for LLMs.