Armenian OCR — Image to Text & PDF
Նկարներից և սկանավորված փաստաթղթերից հայերեն տեքստ հանել
- Armenian alphabet
- Unique characters
- Capital & lowercase
Free image OCR. No account needed. PDFs use pages.
Open OCR for all languagesGoghtn songs classical poetry
Real scan. Unedited OCR.
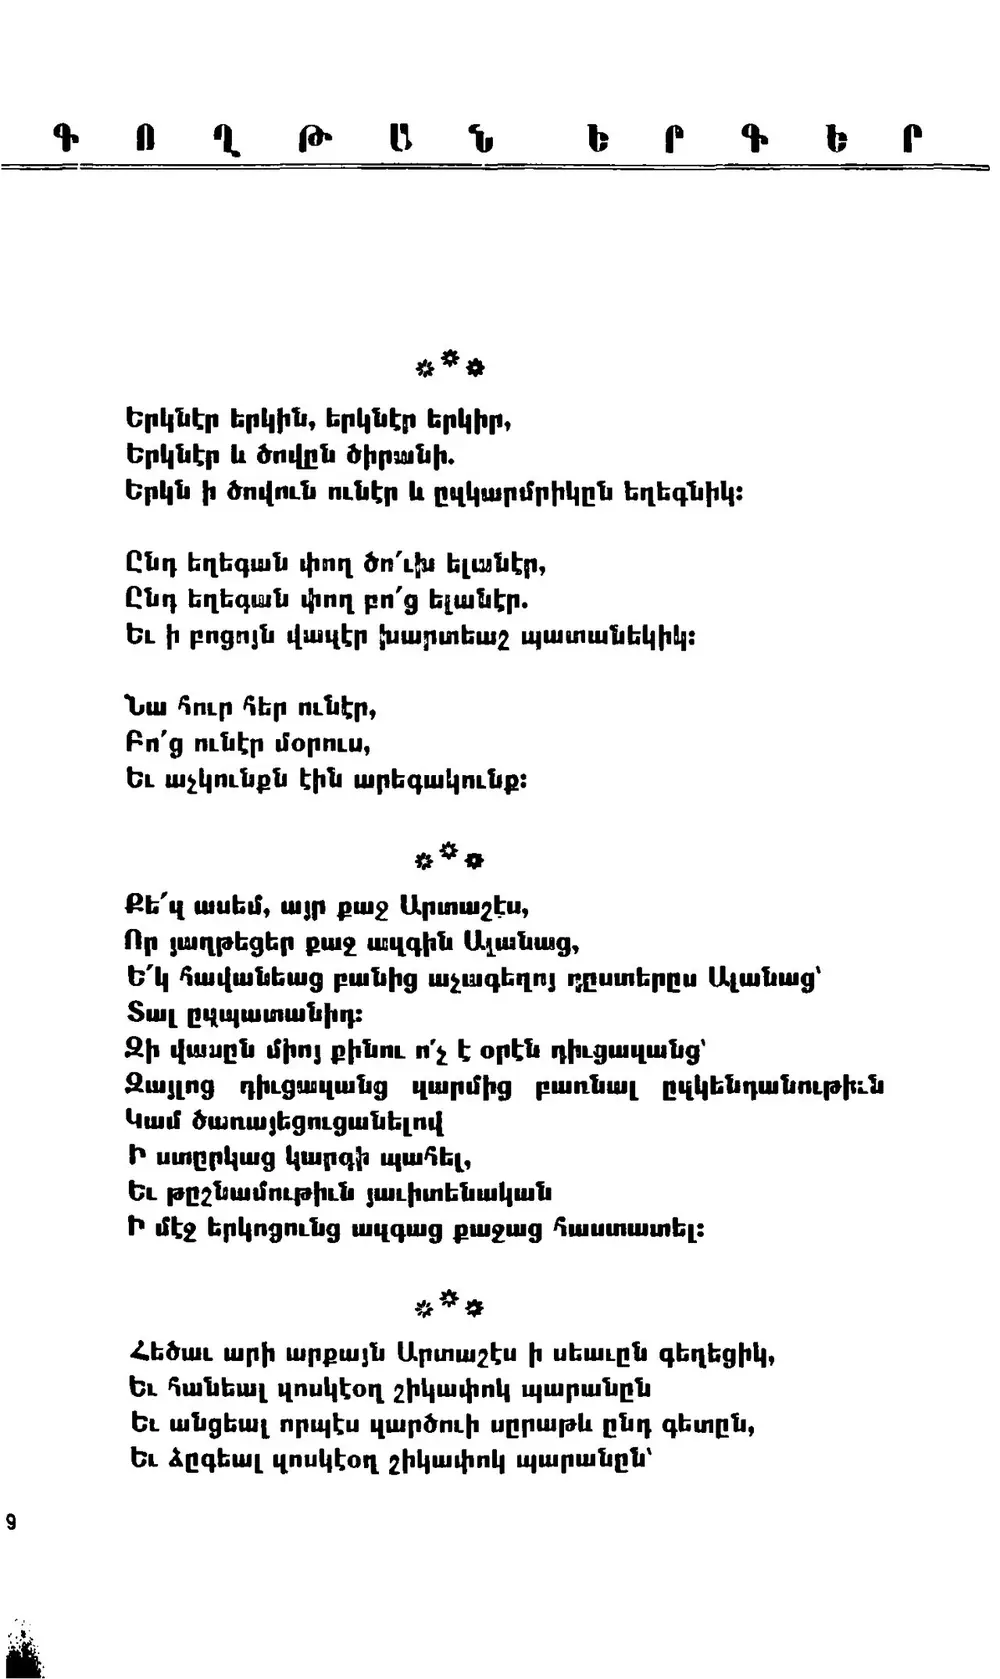
Գ Ո Ղ Թ Թ Ե Ր Գ Ե Ր
Երկնէր երկին, երկնէր երկիր,
Երկնէր և ծովըն ծիրանի.
Երկն ի ծովուն ունէր և ըզկարմրիկըն եղեգնիկ:
Ընդ եղեգան փող ծուխ ելանէր,
Ընդ եղեգան փող բո՛ց ելանէր.
Եւ ի բոցոյն վազէր խարտեաշ պատանեկիկ:
Նա հուր հեր ունէր,
Բո՛ց ունէր մօրուս,
Եւ աչկունքն էին արեգակունք:
Քե՛զ ասեմ, այր քաջ Արտաշէս,
Որ յաղթեցեր քաջ ազգին Ալանաց,
Ե՛կ հավանեաց բանից աչագեղոյ րըստերըս Ալանաց՝
Տալ ըզպատանիդ:
Զի վասըն միոյ քինու ո՛չ է օրէն դիւցազանց՝
Զայլոց դիւցազանց զարմից բառնալ ըզկենդանութիւն
Կամ ծառայեցուցանելով
Ի ստըրկաց կարգի պահել,
Եւ թըշնամութիւն յաւիտենական
Ի մէջ երկոցունց ազգաց քաջաց հաստատել:
Հեծաւ արի արքայն Արտաշէս ի սեաւըն գեղեցիկ,
Եւ հանեալ զոսկէօղ շիկափոկ պարանըն
Եւ անցեալ որպէս զարծուի սըրաթև ընդ գետըն,
Եւ ձըգեալ զոսկէօղ շիկափոկ պարանըն՝
6
Original text order preserved
Armenian OCR converts images, scans and PDFs containing Armenian (Հայերեն) text into editable, searchable digital text. FastOCR reads Armenian online: upload an image with no account, or a PDF with a free account, then copy the text or download a searchable PDF. Accuracy depends on scan quality, so check the result against your original.
Try it with your Armenian document
Drop your file here
PDF, PNG, JPG, WebP, BMP, HEIC
PDF up to 1 GB · images up to 20 MB
Tips for a clear photo
- Lay the page flat.
- Use even light, with no shadows.
- Turn off the flash to avoid glare.
- Fill the frame with the page.
What is Armenian OCR & Developer API?
Developer API docs →Armenian OCR is the automated process of converting scanned multi-page PDFs up to 1GB and documents into editable, searchable Armenian text while preserving accents, complex ligatures, and native character shapes. FastOCR reads printed text in this script and generates full-text searchable PDFs with selectable text overlays. For engineering teams building RAG pipelines, vector search databases, or automated document ingestion, FastOCR also provides a Armenian OCR REST API at api.fastocr.org with 20 free pages a month for every signed-in account. The API accepts PDF files up to 1 GiB, and PNG, JPG, JPEG, GIF, WebP and BMP images up to 20 MiB. An image counts as one page.
Armenian alphabet
Full support for all 38 letters of the Armenian alphabet.
Unique characters
Recognizes Armenian-specific letters like ղ, ճ, փ, ֆ with no Latin equivalent.
Capital & lowercase
Correctly distinguishes Armenian uppercase (Ա-Ֆ) and lowercase (ա-ֆ) forms.
Mixed Armenian & English
Bilingual documents with Armenian and Latin scripts handled in one pass.
Searchable PDF output
Creates PDFs with invisible text layer for full-text search.
Translate after extraction
Extract Armenian text then translate to English or any language.
Why Armenian OCR Is Challenging
- Recognizing unique Armenian characters like ղ, ճ, փ, ֆ which have no equivalent in other scripts
- Distinguishing visually similar Armenian letters like ր/վ, ի/լ, ն/ւ in degraded scans
- Processing documents mixing Armenian with English, Russian, or French text
- Handling the Armenian apostrophe (yeghiya) which functions differently from English apostrophes
- Correctly recognizing Armenian capital letters which are less common in everyday text
How to Extract Armenian Text from a PDF & Images
- Go to fastocr.org
- Upload your Armenian image or PDF. Language is detected automatically.
- Wait for processing — images take seconds, PDFs show a progress bar.
- Download results: searchable PDF, raw text file, or copy text directly.
Tips for Better Armenian OCR Accuracy
- Scan at 300 DPI to preserve the distinctive strokes of Armenian characters
- Verify that Armenian letters are not replaced with similar-looking Latin or Cyrillic characters
- Check capital letters — Armenian capitals (Ա, Բ, Գ...) are used in titles and headings
- For historical documents, expect lower accuracy on classical Armenian (Grabar) text
Common Use Cases for Armenian OCR
- Digitizing Armenian legal documents, contracts, and government records
- Extracting text from Armenian academic papers and university publications
- Converting scanned Armenian newspapers, books, and literary works
- Processing Armenian business invoices and commercial correspondence
- Archiving historical Armenian manuscripts and church documents
FastOCR vs Standard OCR Apps for Armenian
| Capability | FastOCR Dedicated Cloud AI | Standard Online OCR Tools |
|---|---|---|
| Armenian Script Recognition | ✅ Full native cloud recognition for Armenian (complex alphabets and diacritics) | Limited character sets or unhandled accents |
| Multi-Column & Table Layouts | ✅ Preserves proper paragraph and table alignment | Merges unrelated columns together |
| Searchable PDF Output | ✅ Dual-layer searchable PDF with coordinate-aligned text overlay | Plain unformatted text dump only or unsupported |
| Instant Web Access | ✅ Zero software installation (runs in mobile & desktop browser) | Requires local CLI libraries or complex desktop setup |
Frequently Asked Questions
How accurate is Armenian OCR?
FastOCR reads printed Armenian text. The unique alphabet with 38 letters is well-supported by our AI models.
Does Armenian OCR distinguish capitals from lowercase?
Yes. FastOCR correctly identifies Armenian uppercase (Ա-Ֆ) and lowercase (ա-ֆ) forms. Capital letters are used in titles, headings, and sentence beginnings.
Is Armenian OCR free?
Yes. Image OCR is free with no registration. PDF processing requires a free account — see fastocr.org/pricing for plan details.
Can it handle classical Armenian (Grabar) text?
Modern Armenian (Aš̌harhayin) is supported. Classical Armenian (Grabar) used in historical and religious texts has lower accuracy due to archaic character forms.
Dedicated Armenian Tools
Explore Specialized OCR Workflows
FastOCR provides dedicated AI text recognition engines optimized for complex document types and formats:
Free for images. No registration required.
Related Articles & Resources
Georgian OCR
OCR for Georgian — another South Caucasus script
Russian OCR
OCR for Russian — relevant for bilingual Armenian-Russian documents
Image to Text
Convert any image to editable text instantly
PDF to Text
Extract text from scanned and native PDFs
What is OCR?
Learn how optical character recognition technology works.
How Accurate Is OCR?
Discover the accuracy limits of modern OCR technology.
Armenian OCR Guide
Read the complete guide to Armenian OCR and text extraction.
Free Armenian OCR
Upload & Extract TextLast updated: July 24, 2026