Czech OCR — Image to Text & PDF
Extrahujte český text z obrázků a skenovaných dokumentů
- Caron (háček) recognition
- Full diacritics suite
- Ř distinction
Free image OCR. No account needed. PDFs use pages.
Open OCR for all languagesBabicka, 1855
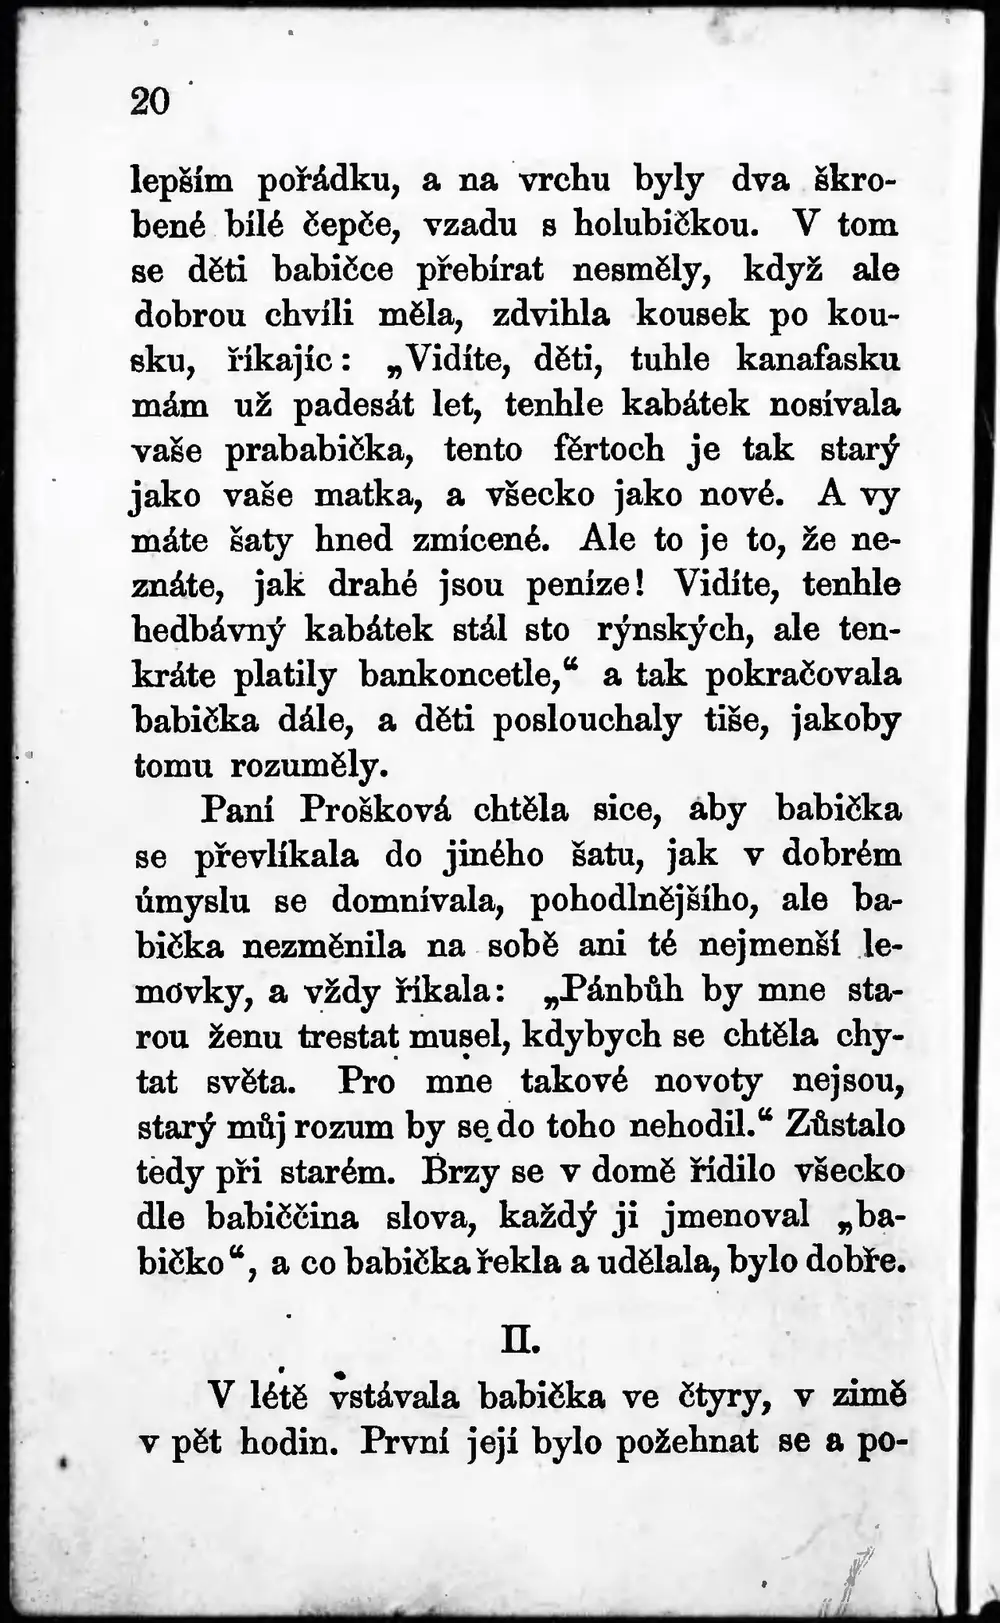
Real scan. Unedited OCR.
20
lepším pořádku, a na vrchu byly dva škro-
bené bílé čepče, vzadu s holubičkou. V tom
se děti babičce přebírat nesměly, když ale
dobrou chvíli měla, zdvihla kousek ро kou-
sku, říkajíc:„Vidíte, děti, tuhle kanafasku
mám už padesát let, tenhle kabátek nosívala
vaše prababička, tento fěrtoch je tak starý
jako vaše matka, a všecko jako nové. A vy
máte šaty hned zmícené. Ale to je to, že ne-
znáte, jak drahé jsou peníze! Vidíte, tenhle
hedbávný kabátek stál sto rýnských, ale ten-
kráte platily bankoncetle," a tak pokračovala
babička dále, a děti poslouchaly tiše, jakoby
tomu rozuměly.
Paní Prošková chtěla sice, aby babička
se převlíkala do jiného šatu, jak v dobrém
úmyslu se domnívala, pohodlnějšího, ale ba-
bička nezměnila na sobě ani té nejmenší le-
movky, a vždy říkala:„Pánbůh by mne sta-
rou ženu trestat musel, kdybych se chtěla chy-
tat světa. Pro mne takové novoty nejsou,
starý můj rozum by se do toho nehodil." Zůstalo
tedy při starém. Brzy se v domě řídilo všecko
dle babiččina slova, každý ji jmenoval„ba-
bičko", a co babička řekla a udělala, bylo dobře.
II.
V létě vstávala babička ve čtyry, v zimě
v pět hodin. První její bylo požehnat se a po-
Original text order preserved
Czech OCR converts images, scans and PDFs containing Czech (Čeština) text into editable, searchable digital text. FastOCR reads Czech online: upload an image with no account, or a PDF with a free account, then copy the text or download a searchable PDF. Accuracy depends on scan quality, so check the result against your original.
Try it with your Czech document
Drop your file here
PDF, PNG, JPG, WebP, BMP, HEIC
PDF up to 1 GB · images up to 20 MB
Tips for a clear photo
- Lay the page flat.
- Use even light, with no shadows.
- Turn off the flash to avoid glare.
- Fill the frame with the page.
What is Czech OCR & Developer API?
Developer API docs →Czech OCR is the automated process of converting scanned multi-page PDFs up to 1GB and documents into editable, searchable Czech text while preserving accents, complex ligatures, and native character shapes. FastOCR reads printed text in this script and generates full-text searchable PDFs with selectable text overlays. For engineering teams building RAG pipelines, vector search databases, or automated document ingestion, FastOCR also provides a Czech OCR REST API at api.fastocr.org with 20 free pages a month for every signed-in account. The API accepts PDF files up to 1 GiB, and PNG, JPG, JPEG, GIF, WebP and BMP images up to 20 MiB. An image counts as one page.
Caron (háček) recognition
Correctly handles ě, š, č, ř, ž with the distinctive háček diacritic.
Full diacritics suite
Recognizes á, é, í, ó, ú, ý (acute accents) and ů (ring) alongside carons.
Ř distinction
Distinguishes ř — the uniquely Czech letter with combined caron + letterform.
Document processing
Works with Czech legal, academic, and business documents.
Searchable PDF output
Creates PDFs with invisible text layer for full-text search.
Translate after extraction
Extract Czech text then translate to English or any language.
Why Czech OCR Is Challenging
- Recognizing the háček (caron) on ě, š, č, ř, ž which can be mistaken for an acute accent in low-quality scans
- Distinguishing ě (e with caron) from plain e and ı in small font sizes — the caron is a small V-shape
- Handling the uniquely Czech letter ř which combines a háček with a serifed letterform
- Processing the ring diacritic on ů which is easily confused with plain u or the degree symbol
- Distinguishing ď and ť from their plain forms d and t — the háček sits beside these tall letters, not above them
How to Extract Czech Text from a PDF & Images
- Go to fastocr.org
- Upload your Czech image or PDF. Language is detected automatically.
- Wait for processing — images take seconds, PDFs show a progress bar.
- Download results: searchable PDF, raw text file, or copy text directly.
Tips for Better Czech OCR Accuracy
- Scan at 300+ DPI to preserve the háček (caron) which is a small V-shape easily lost at low resolution
- Verify that ř is not misread as r, ž, or š — the caron on ř is distinctive and unique to Czech
- Check ů (u-ring) is preserved and not replaced with plain u, ú, or the degree symbol °
- For ď and ť, the háček shifts to a comma-like mark beside the tall letter — verify this is correctly recognized
- Review ě carefully — it looks similar to e-with-acute (é) and is a common OCR confusion point
Common Use Cases for Czech OCR
- Digitizing Czech legal documents, contracts, and court rulings
- Extracting text from Czech government forms and official certificates
- Converting scanned Czech academic papers and university theses
- Processing Czech business invoices and commercial correspondence
- Archiving historical Czech documents and Austro-Hungarian era records
FastOCR vs Standard OCR Apps for Czech
| Capability | FastOCR Dedicated Cloud AI | Standard Online OCR Tools |
|---|---|---|
| Czech Script Recognition | ✅ Full native cloud recognition for Czech (complex alphabets and diacritics) | Limited character sets or unhandled accents |
| Multi-Column & Table Layouts | ✅ Preserves proper paragraph and table alignment | Merges unrelated columns together |
| Searchable PDF Output | ✅ Dual-layer searchable PDF with coordinate-aligned text overlay | Plain unformatted text dump only or unsupported |
| Instant Web Access | ✅ Zero software installation (runs in mobile & desktop browser) | Requires local CLI libraries or complex desktop setup |
Frequently Asked Questions
Does Czech OCR handle all háček characters correctly?
Yes. FastOCR recognizes ě, š, č, ř, ž with the háček (caron) diacritic. The uniquely Czech letter ř is specially handled by our AI models.
How does it handle the letter ů (u with ring)?
FastOCR correctly distinguishes ů from plain u and ú. The ring above ů is a circular diacritic, not an accent mark, and our AI is trained to recognize this distinction.
Can I process scanned Czech PDFs and keep them searchable?
Yes. Upload your scanned Czech PDF and FastOCR creates a searchable version with selectable Czech text, preserving diacritics and original layout.
Is Czech OCR free?
Image OCR is free with no registration. PDF processing requires a free account — see fastocr.org/pricing for plan details.
Dedicated Czech Tools
Explore Specialized OCR Workflows
FastOCR provides dedicated AI text recognition engines optimized for complex document types and formats:
Free for images. No registration required.
Related Articles & Resources
Slovak OCR
OCR for Slovak — closely related West Slavic language
Polish OCR
OCR for Polish — another West Slavic language with rich diacritics
German OCR
OCR for German — relevant for bilingual Czech-German documents
Image to Text
Convert any image to editable text instantly
PDF to Text
Extract text from scanned and native PDFs
What is OCR?
Learn how optical character recognition technology works.
How Accurate Is OCR?
Discover the accuracy limits of modern OCR technology.
Czech OCR Guide
Read the complete guide to Czech OCR and text extraction.
Free Czech OCR
Upload & Extract TextLast updated: July 24, 2026